FRTE 1:1 Verification
These comments provided by Neurotechnology are based on NIST FRTE 1:1 Verification ongoing evaluation results reviewed on October 19, 2026.
NIST FRTE 1:1 Verification evaluates how well face recognition technologies work across various uses, from visa and mugshot photo comparisons to border crossing and kiosk images. NIST currently reports results for six testing scenarios. Algorithms' accuracy is the primary assessment metric, with additional metrics like matching speed and memory consumption. Most images contain one face; some of the border and kiosk images contain more than one.
See FRTE official page for more information.
The Face Recognition Technology Evaluation (FRTE) started in July, 2023, as a successor of the previous FRVT Ongoing evaluation of face verification algorithms. The FRTE 1:1 Verification track allows vendors to submit multiple algorithms once every three months. The NIST summary table lists one algorithm per developer, 451 in the current results.
Neurotechnology algorithm submission (neurotechnology-021) has been ranked as one of the most accurate for border control supervised (Visa Border, Border) and unsupervised (Border-Kiosk) scenarios among the developers listed by NIST. The results for each scenario are presented below:
- FRTE 1:1 Mugshot Photos
- FRTE 1:1 Mugshot Photos ΔT >12 YRS
- FRTE 1:1 Visa vs Border Photos
- FRTE 1:1 Visa vs Border Yaw ≥45° Photos
- FRTE 1:1 Border Photos
- FRTE 1:1 Border vs. Kiosk Photos
For each scenario, we report three results:
- Neurotechnology result
- Best contender result
- Median result: the middle value of the scenario results in the NIST Accuracy By Developer table, which lists one algorithm per developer, Neurotechnology included. Only developers with a result in that scenario are counted. When their number is even, the median is the average of the two middle values.
Mugshot
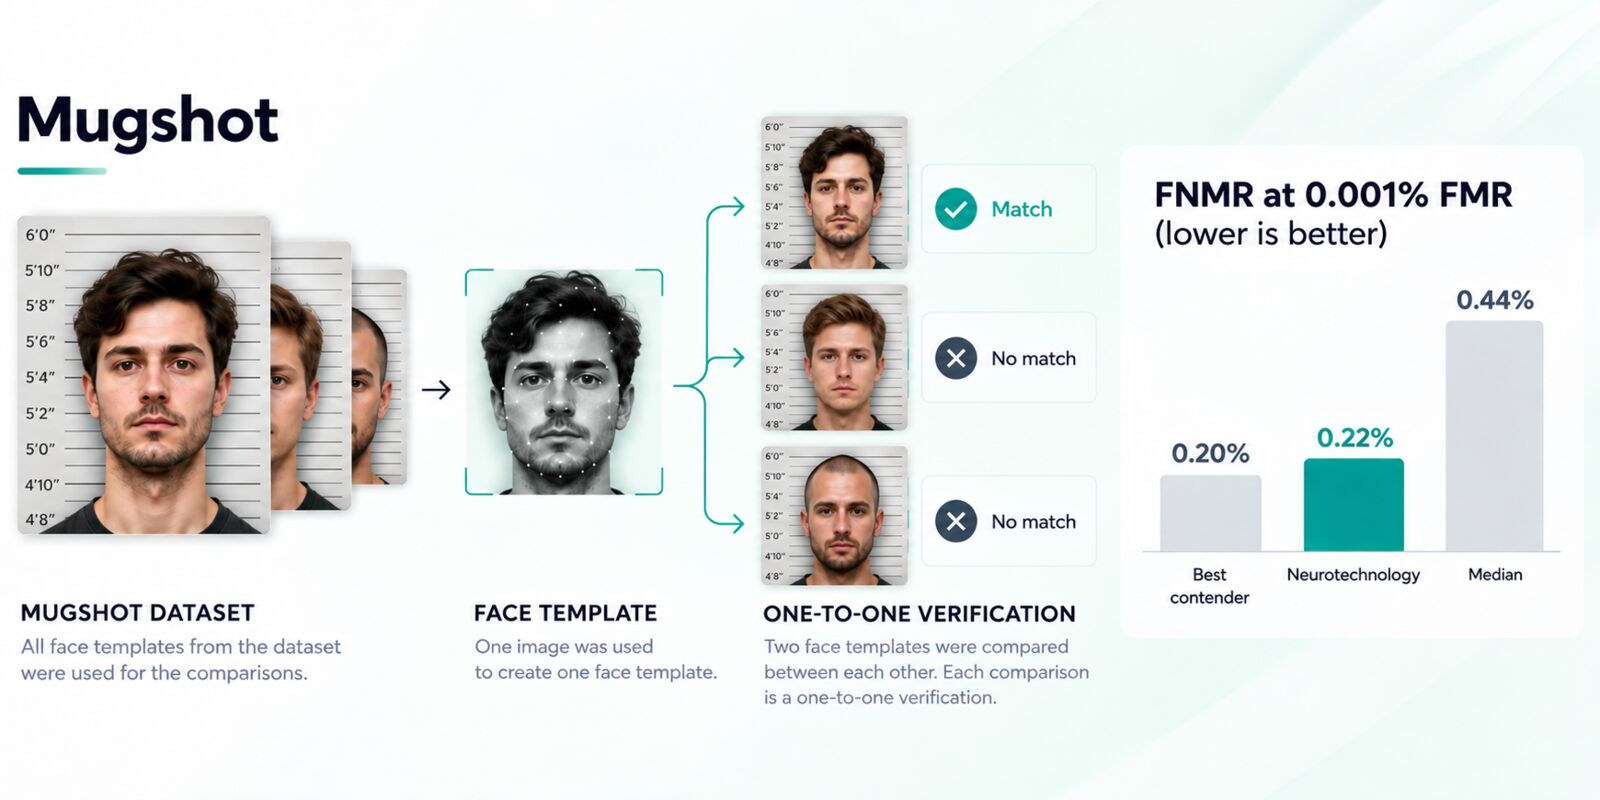
The comparisons were performed between all face templates from the MUGSHOT dataset.
Algorithm accuracy in this scenario at 0.001% FMR:
- Neurotechnology result: 0.22% FNMR
- Best contender result: 0.20% FNMR
- Median result: 0.44% FNMR
Scenario overview
- One image from the dataset was used to create one face template.
- All face templates were compared between each other.
- Each comparison score was obtained by comparing two different templates (simple one-to-one verification).
- Gender attribute was used to exclude comparisons between different gender subjects.
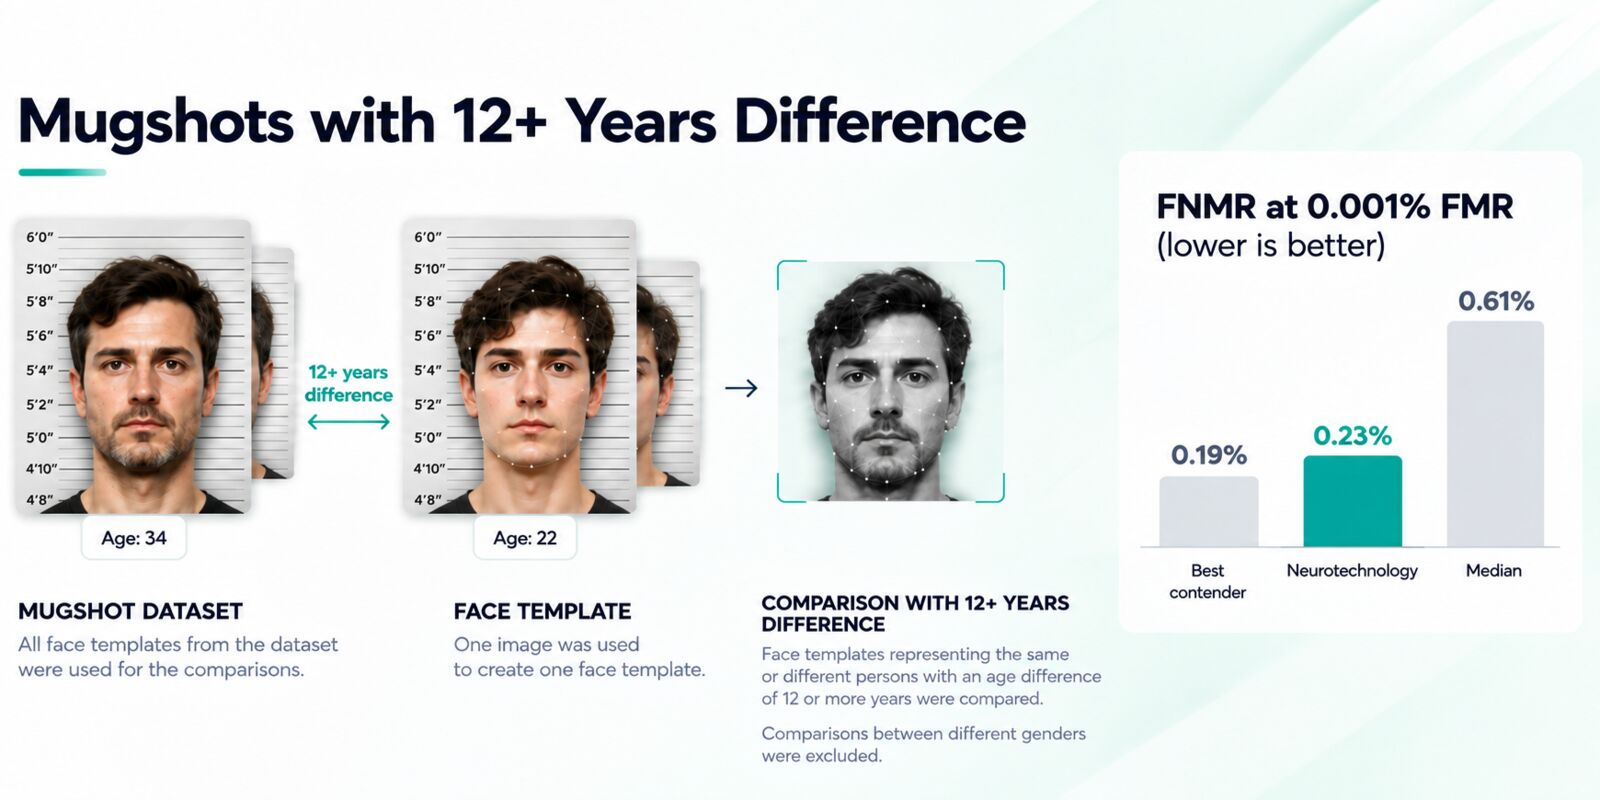
Mugshots with 12+ years difference
The test was performed using facial templates, generated from the MUGSHOT dataset. The comparisons were performed only between templates representing same or different persons with age difference of 12 or more years between them.
Algorithm accuracy in this scenario at 0.001% FMR:
- Neurotechnology result: 0.23% FNMR
- Best contender result: 0.19% FNMR
- Median result: 0.61% FNMR
Scenario overview
- One image from the MUGSHOT dataset was used to create one face template.
- Age attribute was used to exclude template pairs, which represented same or different persons with age difference of less than 12 years at the capture moment, from the comparison.
- Gender attribute was used to exclude comparisons between different gender subjects.
- Each comparison score was obtained by comparing two different templates (simple one-to-one verification).
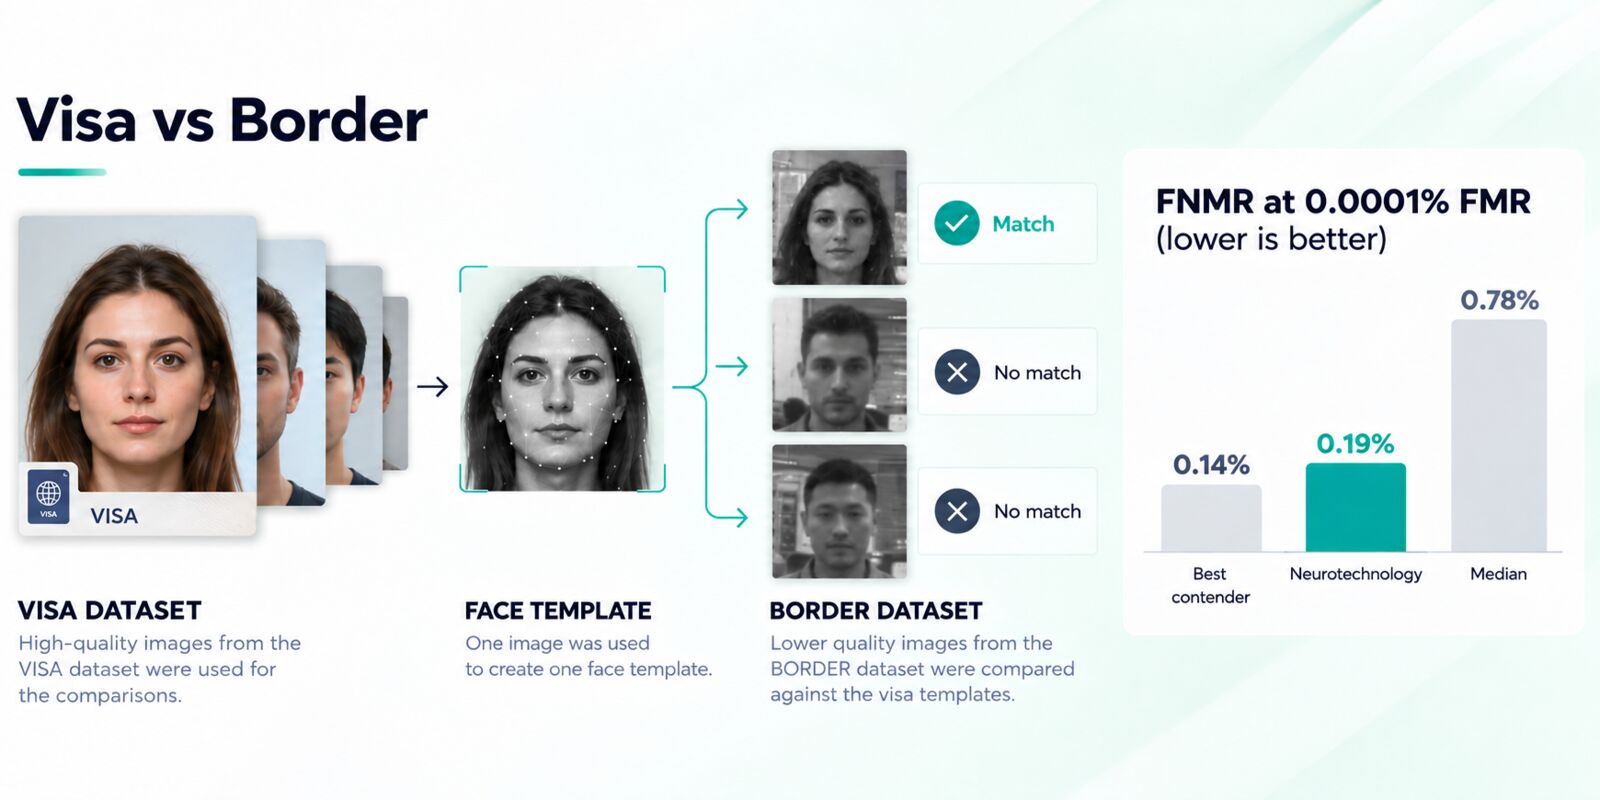
Visa vs Border
The test was performed by comparing high-quality images from the VISA dataset against lower quality images from the BORDER dataset. Both datasets include subjects from more than 100 countries, with specific imbalances due to visa issuance patterns and border-crossing demographics correspondingly.
Algorithm accuracy in this scenario at 0.0001% FMR:
- Neurotechnology result: 0.19% FNMR
- Best contender result: 0.14% FNMR
- Median result: 0.78% FNMR
Scenario overview
- One image from Visa or Border datasets was used to create one face template.
- Gender attribute was used to exclude comparisons between different gender subjects.
- Each pre-filtered template from the Visa dataset was compared against each pre-filtered template from the Border dataset
- Each comparison score was obtained by comparing two different templates (simple one-to-one verification).
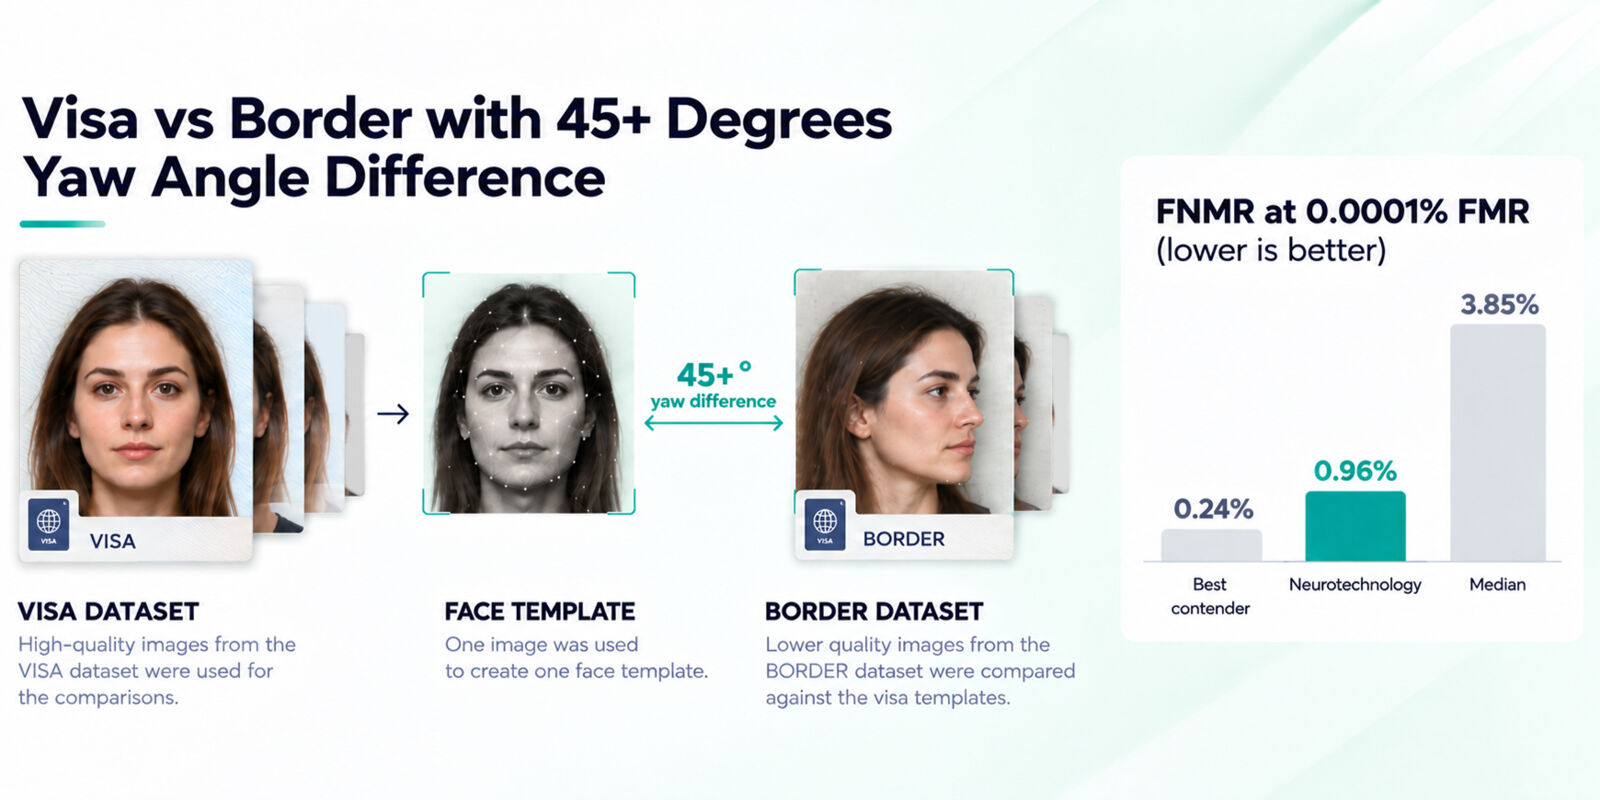
Visa vs Border with 45+ degrees yaw angle difference
The test was performed by comparing high-quality images from the VISA dataset against lower quality images from the BORDER dataset. The comparisons were performed only between photos representing same or different persons with face yaw angle difference of 45 or more degrees between them.
Algorithm accuracy in this scenario at 0.0001% FMR:
- Neurotechnology result: 0.96% FNMR
- Best contender result: 0.24% FNMR
- Median result: 3.85% FNMR
Scenario overview
- One image from Visa or Border datasets was used to create one face template.
- Gender attribute was used to exclude comparisons between different gender subjects.
- Face yaw angle attribute was used to filter face template pairs for achieving the required yaw angle difference of 45 or more degrees.
- Each pre-filtered template from the Visa dataset was compared against each pre-filtered template from the Border dataset
- Each comparison score was obtained by comparing two different templates (simple one-to-one verification).
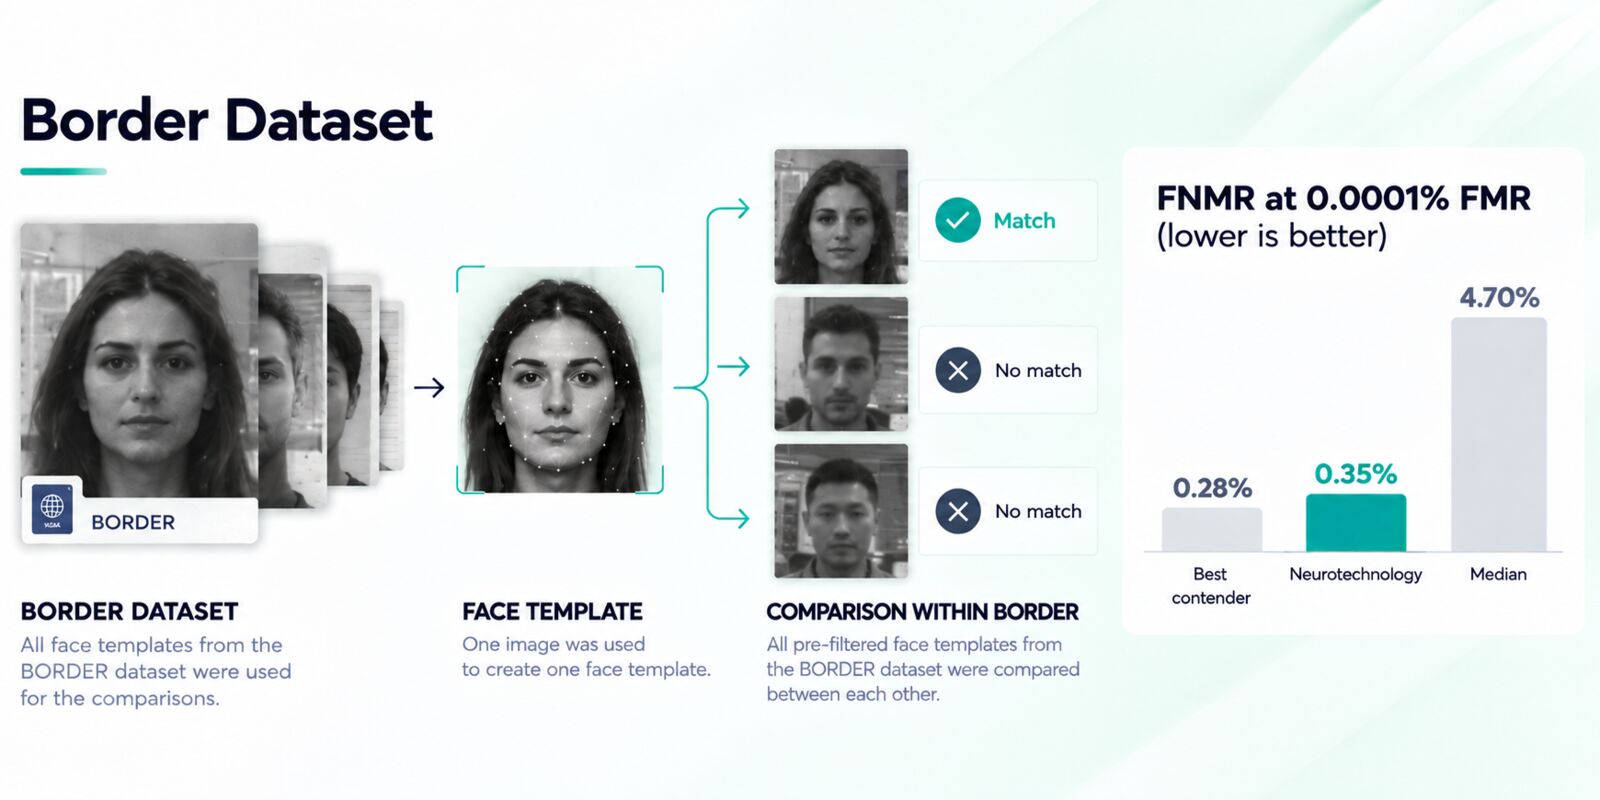
Border
The comparisons were performed between face templates from the BORDER dataset, using gender attribute to exclude comparisons between different gender subjects.
Algorithm accuracy in this scenario at 0.0001% FMR:
- Neurotechnology result: 0.35% FNMR
- Best contender result: 0.28% FNMR
- Median result: 4.70% FNMR
Scenario overview
- One image from the dataset was used to create one face template.
- Gender attribute was used to exclude comparisons between different gender subjects.
- All pre-filtered face templates were compared between each other.
- Each comparison score was obtained by comparing two different templates (simple one-to-one verification).
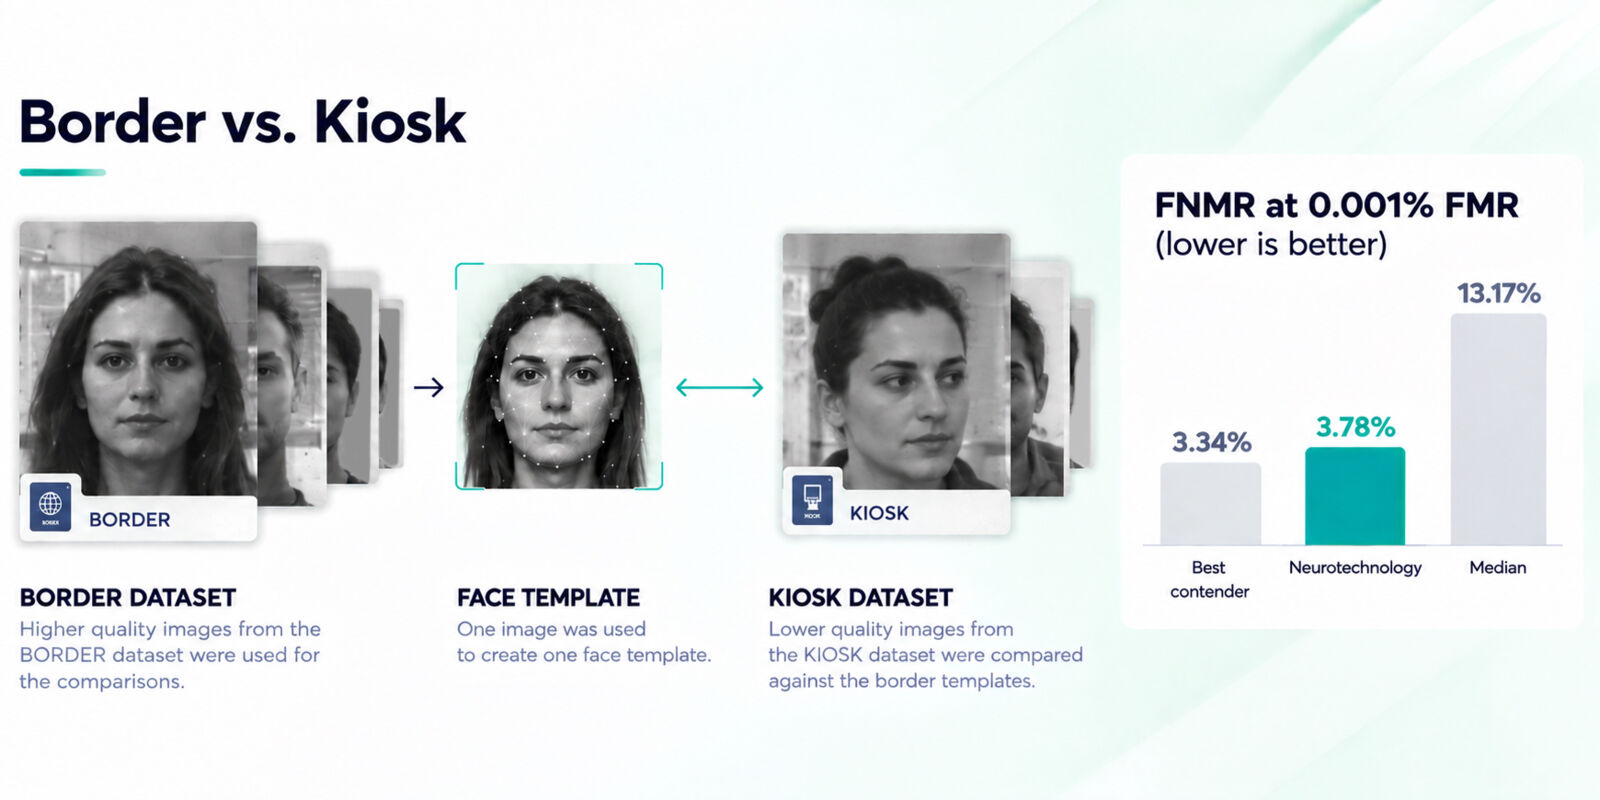
Border vs. Kiosk
The test was performed by comparing higher quality images from the BORDER dataset against lower quality images from the KIOSK dataset. The BORDER dataset includes subjects from more than 100 countries, with significant imbalance due to population and immigration patterns.
The dataset is made from images, which were captured from cooperating subjects in a partially controlled environment. Images' quality varied due to an automated, non-supervised capture method.
Algorithm accuracy in this scenario at 0.001% FMR:
- Neurotechnology result: 3.78% FNMR
- Best contender result: 3.34% FNMR
- Median result: 13.17% FNMR
Scenario overview
- One image from each dataset was used to create one face template.
- Gender attribute was used to exclude comparisons between different gender subjects.
- All pre-filtered face templates from one dataset were compared with all pre-filtered templates from the other dataset.
- Each comparison score was obtained by comparing two different templates (simple one-to-one verification).
Datasets Summary
VISA dataset
The dataset represents typical photos of US visa applicants. According to the dataset description, the face images are generally high quality. Part of the images are live capture and the other part is photographed from paper photos.
- More than 100,000 unique persons.
- Part of the images are live capture and part are digitized paper photos.
- High quality images, with conformance with the ISO/IEC 19794-5 Full Frontal image type. Subjects' pose is generally excellent.
- Image size: 252x300 pixels.
- Interocular distance (IOD): 69 pixels.
- Subjects from more than 100 countries are represented, with significant imbalance due to visa issuance patterns.
- All ages are represented, including children, with imbalance due to visa issuance demand.
MUGSHOT dataset
The dataset represents typical photos of suspects taken by law enforcement officers. The photos were taken in a controlled environment thus their quality is high.
- More than 1,000,000 unique persons.
- All images were live capture.
- High quality images, with conformance with the ISO/IEC 19794-5 Full Frontal image type. Subjects' pose is generally excellent.
- Variable image sizes.
- Interocular distance (IOD): from 34 to 297 pixels, with 113 pixels mean and 105 pixels median values.
- All subjects are from the United States.
- All subjects are adults.
Border dataset
The dataset is made of images obtained at border crossing. Images are taken by operators with webcams oriented towards cooperating subjects. The quality of the images may vary due to time-constrained capture and different illumination conditions.
- More than 1,000,000 unique persons.
- All images were live capture
- Variable image quality. There are roll, pitch and yaw angle variations. There is some perspective distortion due to close range images. Background illumination is sometimes strong, so faces may be under-exposed. Some faces are partially cropped.
- Interocular distance (IOD): 38 pixels mean.
- Subjects from more than 100 countries are represented, with significant imbalance due to immigration patterns.
- Subjects are adults and children aged 12 or above, with age distribution imbalance due to immigration patterns.
KIOSK dataset
The dataset is made from images, which were captured from cooperating subjects in a partially controlled environment. Images' quality varied due to an automated, non-supervised capture method.
- All images were live capture.
- Many images have a considerable downward pitch angle.
- In some images, faces are partially cropped.
- Some images have other faces in the background.
Disclaimers:
- The images on this page next to each test scenario are AI-generated synthetic visuals and are provided solely for illustrative purposes. They do not depict or correspond to any real person. No images from the datasets used in the NIST evaluation were used, in any way, to create these illustrations.